One model, not two.
It talks, and it decides from the same memory.
Open source · coming soon
talks · thinks · decides
see the numbers ↓
see the numbers ↓
see the numbers ↓
// in plain numbers
Same size. Smarter decisions.
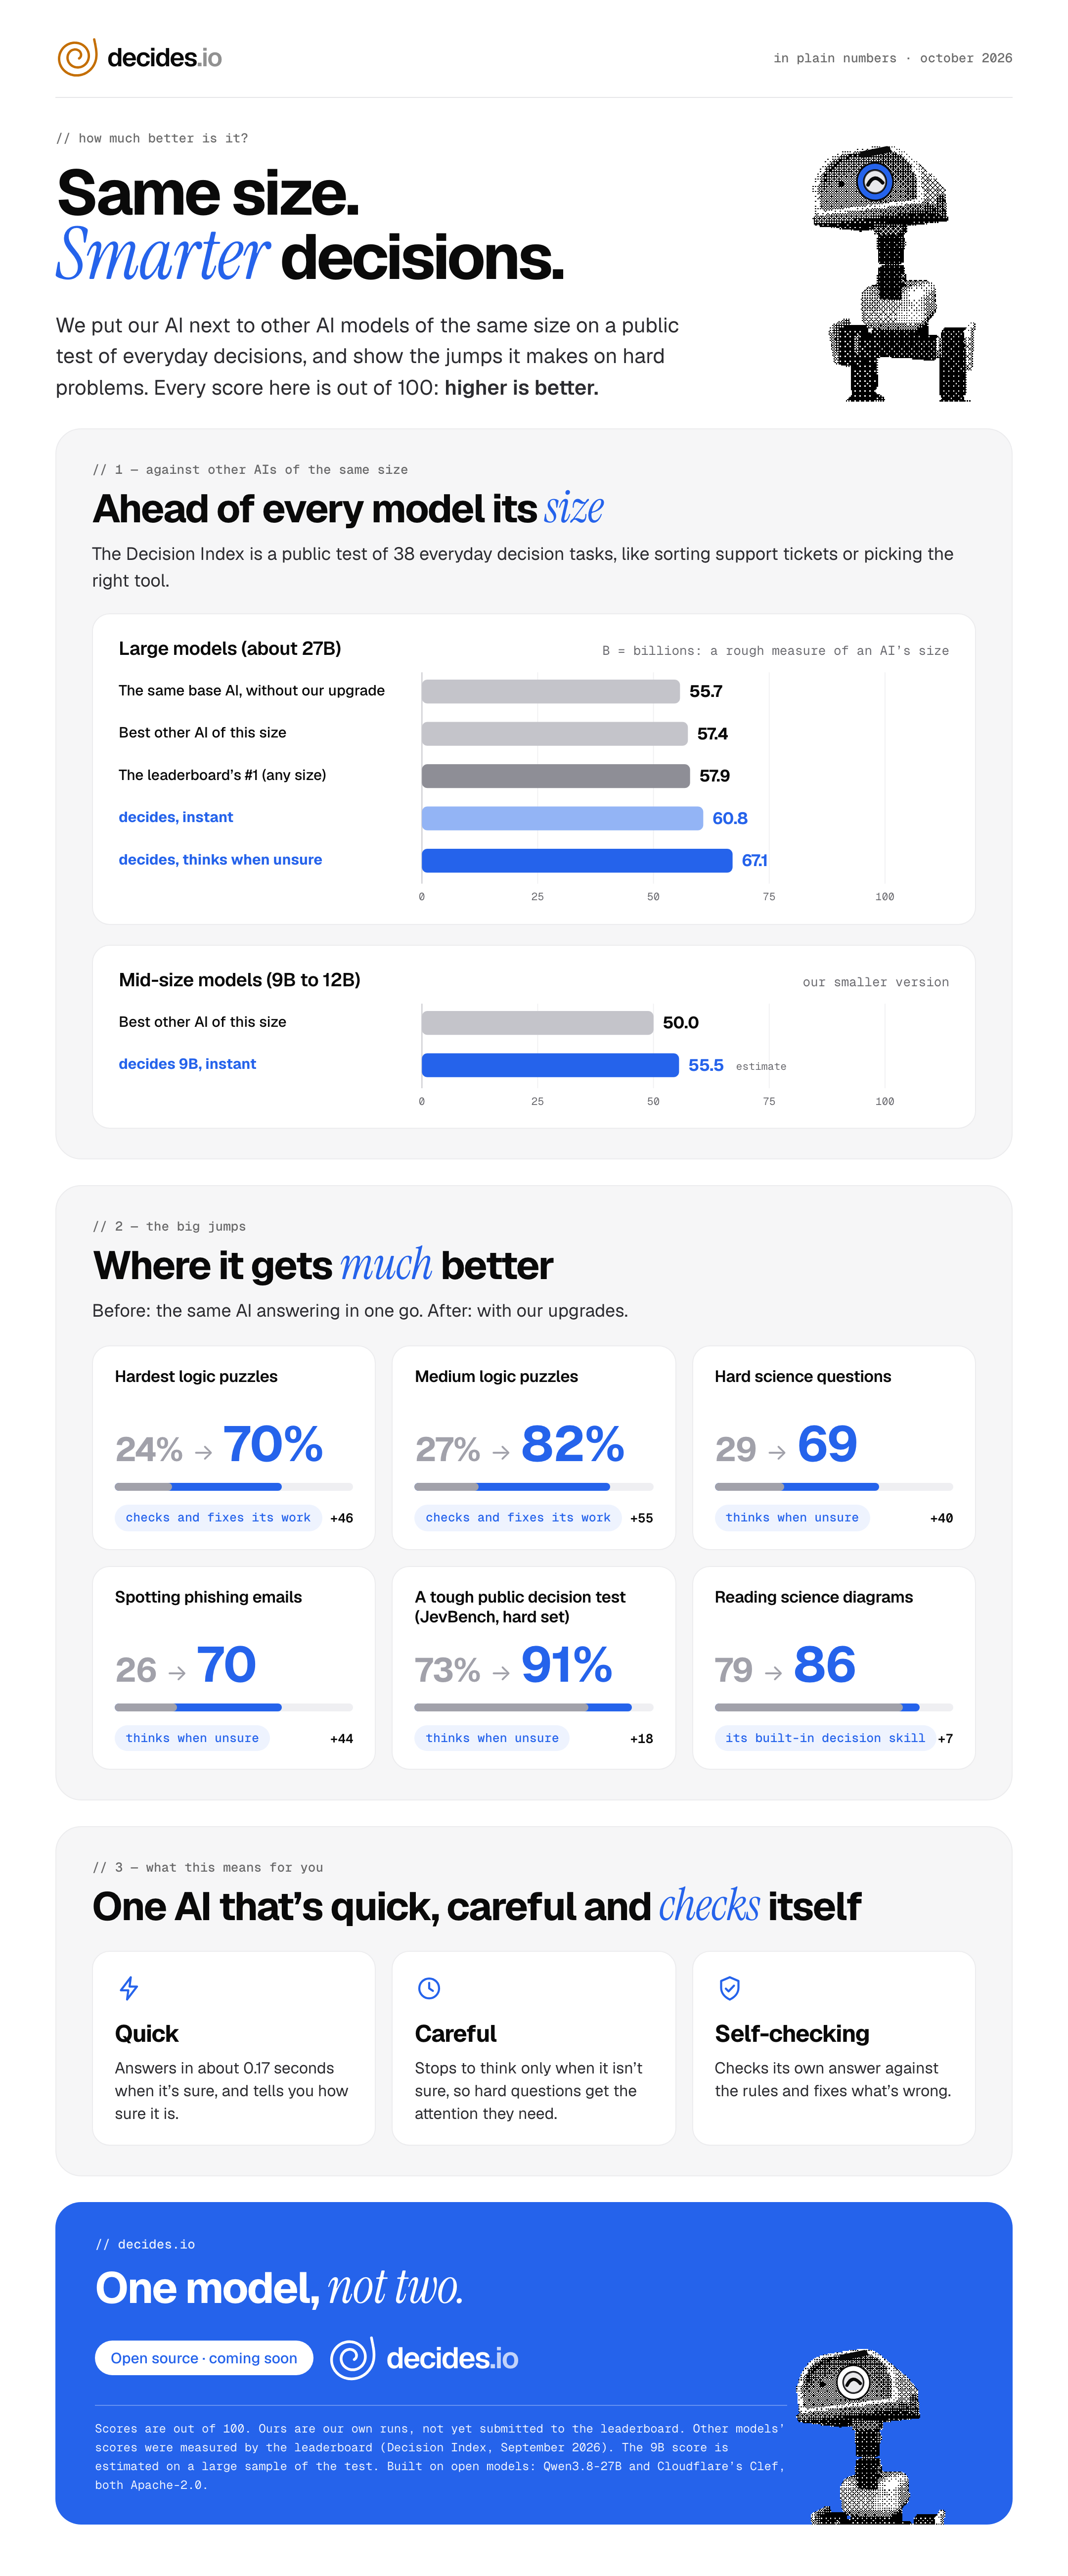
We put decides next to other AI models of the same size on the Decision Index, a public test of 38 everyday decision tasks. Every score is out of 100: higher is better.
Large models (about 27B)
B = billions: a rough measure of an AI’s size050100
Mid-size models (9B to 12B)
our smaller versionWhere it gets much better
Before: the same AI answering in one go. After: with our upgrades.
Hardest logic puzzles
24%→70%
checks and fixes its workMedium logic puzzles
27%→82%
checks and fixes its workHard science questions
29→69
thinks when unsureSpotting phishing emails
26→70
thinks when unsureA tough public decision test (JevBench, hard set)
73%→91%
thinks when unsureReading science diagrams
79→86
its built-in decision skillQuick
Answers in about 0.17 seconds when it’s sure, and tells you how sure it is.
Careful
Stops to think only when it isn’t sure, so hard questions get the attention they need.
Self-checking
Checks its own answer against the rules and fixes what’s wrong.
Scores are out of 100. Ours are our own runs, not yet submitted to the leaderboard. Other models’ scores were measured by the leaderboard (Decision Index, September 2026). The 9B score is an estimate from a large sample of the test. Built on open models: Qwen3.8-27B and Cloudflare’s Clef, both Apache-2.0.